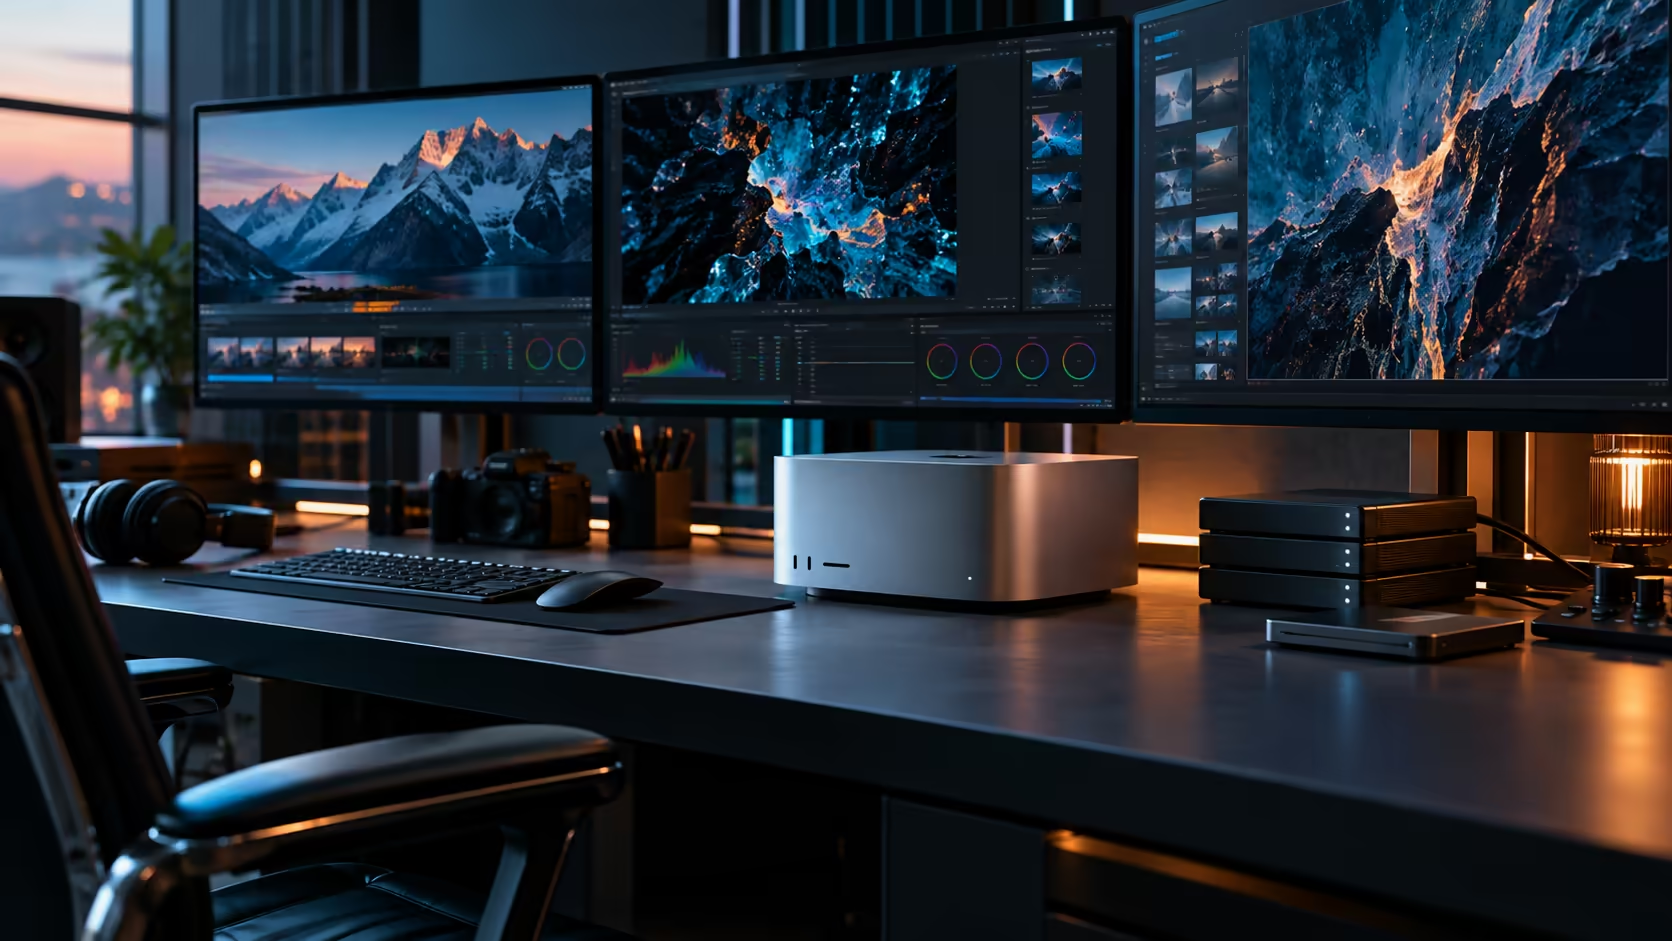
Put two demanding tasks on a Mac Studio M5 Ultra at the same time, an 8K export and a local AI model, and the question that actually decides whether both run smoothly isn't how much memory each one needs. It's whether the pipe connecting that memory to the chip is wide enough to feed both at once.
Quick Answer
When multiple demanding tasks run on a Mac Studio M5 Ultra simultaneously, memory bandwidth, not capacity, decides whether they interfere with each other. The 96GB pool holds plenty of room for both an 8K export and an AI model, but if the combined data movement exceeds what the chip's memory bandwidth can sustain, both tasks slow down together rather than one failing outright. The Mac Studio M5 Ultra with that 96GB pool is R108,999.
🚦 Why concurrent workloads test bandwidth, not just capacity
A single heavy task rarely comes close to saturating available bandwidth on its own. Running two or three at once is where the picture changes.
An 8K (7680x4320) export reading and writing large frames, a local AI model processing tokens, and a background render all pull from the same shared bandwidth pool simultaneously when running together. None of them individually need the chip's full bandwidth capacity, but their combined demand can approach it during genuine overlap, which is the scenario a single-task benchmark never reveals.
👥 What this means for a shared or multi-tasking workstation
This is precisely the situation a halo machine running several jobs, or several people, tends to create.
Two editors grading separate timelines at once, or one person exporting while another runs a model, both draw on the identical 96GB bandwidth pool the M5 Ultra's architecture provides. The Ultra's higher bandwidth over the Max tier exists specifically to give this kind of concurrent, multi-task load more room before any single task visibly slows, which is a genuinely different justification for the higher tier than simply "more memory."
📉 What it looks like when bandwidth, not capacity, is the limit
The two failure modes look different in practice, and recognising which one you're seeing points to a different fix.
Running out of a fixed 96GB memory capacity typically means a task fails to load or crashes outright. Running short on bandwidth under heavy concurrent load instead shows up as everything running, but more slowly, than any single task would alone, footage playback getting choppy, a model responding more sluggishly, a render taking longer than its solo benchmark suggested. If your combined workload shows the second pattern, adding memory won't fix it; reducing how many demanding tasks genuinely overlap will.
🔍 Where to check the actual figure, and why it's still one input among several
For the M5 Ultra's precise bandwidth rating, Apple's own technical documentation is the authoritative source.
That number matters most for exactly the concurrent scenario described above, less so for a single task running in isolation, where capacity and processing power usually matter more first. Weigh it alongside your realistic concurrent workload on this R108,999 machine rather than treating it as the headline figure that alone decides whether this tier suits you.
🖥️ How concurrent load differs on a discrete-GPU workstation
A traditional tower handles simultaneous heavy tasks through a different mechanism entirely, and the comparison is worth making honestly.
A discrete graphics card has its own dedicated VRAM bandwidth, separate from system memory, unlike the 96GB pool this chip shares across every task, so a GPU-bound task and a CPU-bound task on a Windows workstation don't compete for the identical bandwidth pool the way two GPU-heavy or memory-heavy tasks do on a unified architecture. This can be an advantage for specific mixed workloads and a disadvantage for workloads that need to move data between CPU and GPU repeatedly, which is the same trade-off unified memory makes everywhere else.
🧮 Deciding whether this concurrency question applies to you
Not every buyer needs to think this hard about bandwidth, and it's worth being honest about who genuinely does.
If your work is one demanding task at a time, editing, then exporting, then moving to the next project, this concern barely applies, and comparing this configuration against the wider compact PC lineup on capacity alone is enough. If your day genuinely involves several heavy tasks or several people working the machine at once, weigh this concurrent-bandwidth question seriously against a dedicated workstation build with its own separate GPU memory, since that architecture handles a specific kind of concurrent load differently.
🔧 A practical way to test your own concurrent load
Simulate your actual worst overlap before committing to a configuration on the strength of a spec sheet number.
Start your heaviest export or render, then load and query an AI model alongside it, then check whether either one noticeably slows within the first 10 minutes compared to running alone. If both hold up, your realistic concurrent load fits comfortably within what this chip provides. If either visibly degrades, that's the signal to either reduce how much you run simultaneously or size your next machine around this specific concurrent scenario rather than around any single task's isolated benchmark figure.
Frequently Asked Questions
Does running two demanding tasks at once on the M5 Ultra cause one to fail?
Not typically from a bandwidth limit alone. The more common symptom is both tasks slowing down together rather than either one failing outright.
How do I know if my slowdown is a bandwidth issue rather than a memory capacity issue?
Capacity problems usually show as a task failing to load or crashing. Bandwidth problems under concurrent load show as everything running, but noticeably slower than any single task's own benchmark would suggest.
Does the M5 Ultra have more memory bandwidth than the M5 Max specifically to help with concurrent tasks?
Its higher bandwidth benefits exactly this kind of scenario, giving more room before concurrent demanding tasks start visibly competing with each other.
Should I worry about bandwidth if I only ever run one task at a time?
Less so. Bandwidth limits matter most under genuine concurrent load; a single task running alone rarely comes close to saturating what this chip provides.
Is a discrete-GPU workstation ever a better choice than unified memory for concurrent tasks?
For a mix of one CPU-heavy and one GPU-heavy task running side by side, yes, since a discrete card's separate VRAM avoids the shared-pool contention unified memory can experience under that specific combination.
Ready to plan for genuinely concurrent workloads on a Mac Studio M5 Ultra?
Compare unified memory bandwidth against your team's real overlapping demands before committing.