


Fix Dead pixel checks on RX 9070 XT build
Dead pixel on RX 9070 XT build needs careful display-chain checks, not a single-part blame. Test the screen, cable, port, scaling, drivers, and setup context before replacing hardware.
Read moreHardware delivery to Plettenberg Bay should be shortlisted around the job it must do. South African buyers should compare fit, performance, compatibility, and upgrade room, warranty path, and upgrade room before treating any pick as best.
Running local LLMs comes down to VRAM: a 24GB card runs a 13B model comfortably, while 16GB handles 7-8B models fast. An RTX 5080-class build does this well in Plettenberg Bay for around R40,000, and more system RAM extends what you can offload.
Local LLMs (Llama, Mistral, Qwen) load into VRAM. 16GB runs a 7-8B model at full speed; 24GB comfortably fits a 13B model, and quantised (4-bit) versions stretch this further. The RTX 5080 (16GB) or higher is the practical target. Tokens-per-second scale with memory bandwidth, so newer cards generate noticeably faster.
When a model exceeds VRAM, layers offload to system RAM - so 64GB DDR5 lets you run larger models slowly and keep big context windows. A fast Ryzen 7/9 helps CPU-offloaded layers. A 2TB Gen4 NVMe (from R2,200) stores multiple multi-gigabyte model files for quick switching.
Tools like Ollama or LM Studio make local models easy to run. holiday-town peak-season delays makes good cooling worthwhile under sustained inference. Evetech ships to Plettenberg Bay in 3-5 working days off the N2. On arrival, install the latest driver and benchmark tokens-per-second on a 7B model to set expectations.
16GB runs 7-8B models at full speed; 24GB comfortably fits a 13B model. Quantised 4-bit versions let larger models fit in less VRAM with a small quality trade-off.
Yes, slowly - layers offload to system RAM, so 64GB DDR5 lets you run larger models on CPU. A strong GPU is far faster, but RAM offload is a workable budget path.
Evetech reaches Plettenberg Bay in 3-5 working days off the N2. Install Ollama or LM Studio on arrival and benchmark a 7B model to confirm tokens-per-second.
Run models locally, privately An RTX 5080-class GPU with 64GB DDR5 runs 13B models on your own machine in Plettenberg Bay. Browse Evetech's AI-ready PCs and start with Ollama to benchmark tokens-per-second on a 7B model.
Dead pixel on RX 9070 XT build needs careful display-chain checks, not a single-part blame. Test the screen, cable, port, scaling, drivers, and setup context before replacing hardware.
Read more
Genshin Impact anti-cheat error on RTX 4090 usually needs service, permissions, overlay, and file integrity checks. Use this SA-focused fix path to isolate launch blockers before reinstalling or changing security settings.
Read more
Mass Effect launch trouble on RX 7800 XT needs focused driver, settings, launcher, and heat checks. Use this SA-friendly guide to isolate the likely cause, protect saves, and return to smoother play without unsupported hardware claims.
Read more
144Hz 1440p setup for video editing in 1080p - what SA needs a balanced, cautious look before buying. Compare fit, budget, workload, warranty support, and upgrade room so the choice makes sense for South African buyers.
Read more
R8,000 gaming PC build in KwaZulu-Natal needs a practical check before you shortlist anything. Compare fit, compatibility, warranty support, timing, and total setup balance for South African buyers.
Read more
Brits video editing in 4K build under R20,000 needs a balanced parts plan, not a random basket. Map the CPU, GPU, RAM, SSD, cooling, and monitor target to the budget so SA builders know where to spend first.
Read more
Windows never combine taskbar shows separate labelled buttons for open windows. Choose it in Taskbar behaviours, then review space and other-display settings; labels and grouping are linked in the available options.
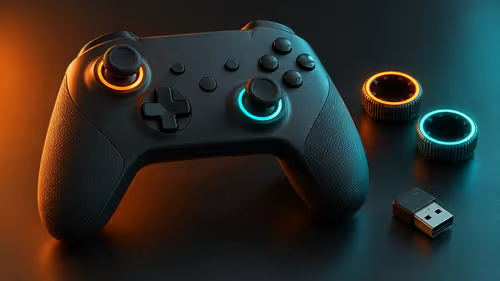
8BitDo Ultimate 3C+ brings adjustable stick tension to the C Series. Windows uses wired USB or the 2.4 GHz adapter; Android uses Bluetooth. Confirm those modes and local pricing before buying.
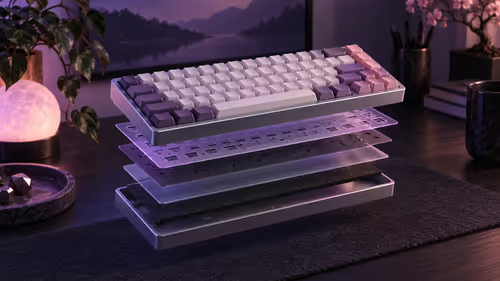
EPOMAKER Galaxy75 previews an aluminium 75% keyboard with wireless modes and HUB/VIA customisation. It is still marked coming soon; final pricing and South African supply are not confirmed.
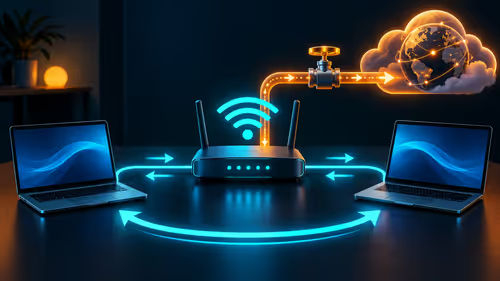
Windows Delivery Optimisation can share update files with other PCs. Review its activity, choose local-only sharing or turn peer sharing off, and use bandwidth controls; those choices do not disable Windows Update.
Windows never combine taskbar shows separate labelled buttons for open windows. Choose it in Taskbar behaviours, then review space and other-display settings; labels and grouping are linked in the available options.
Windows Delivery Optimisation can share update files with other PCs. Review its activity, choose local-only sharing or turn peer sharing off, and use bandwidth controls; those choices do not disable Windows Update.
Windows touch indicator adds visual feedback where you touch a screen. Change it in Accessibility, Mouse pointer and touch; a feedback circle is different from inaccurate input, ghost touches or a damaged panel.
Windows underline access keys makes supported menu letters easier to see. Enable the keyboard accessibility option, then follow the app's displayed Alt cues; this does not remap keys or create missing app shortcuts.
Windows Task View button visibility is a taskbar preference. Hide it in Taskbar settings if you prefer Windows plus Tab, and keep virtual desktop switching separate from closing your applications.
Windows taskbar search box display options can free space without removing search. Choose Hide, an icon or a box in Taskbar settings, then use Windows plus S when you need to search.
Windows text suggestions can offer word choices while you type with a physical keyboard. Enable the setting under Typing, test a supported app, and keep suggestions separate from automatic corrections.
Windows autocorrect settings and application spelling tools are separate controls. Change one at a time, test a harmless sentence, and keep useful spelling highlights if automatic replacements get in your way.