


Fix Monitor stuck at 60Hz checks on DDR5 build
Monitor stuck at 60Hz on DDR5 build needs careful display-chain checks, not a single-part blame. Test the screen, cable, port, scaling, drivers, and setup context before replacing hardware.
Read moreSetting up a running local LLMs rig in Hermanus should be shortlisted around the job it must do. South African buyers should compare fit, performance, compatibility, and upgrade room, warranty path, and upgrade room before treating any pick as best.
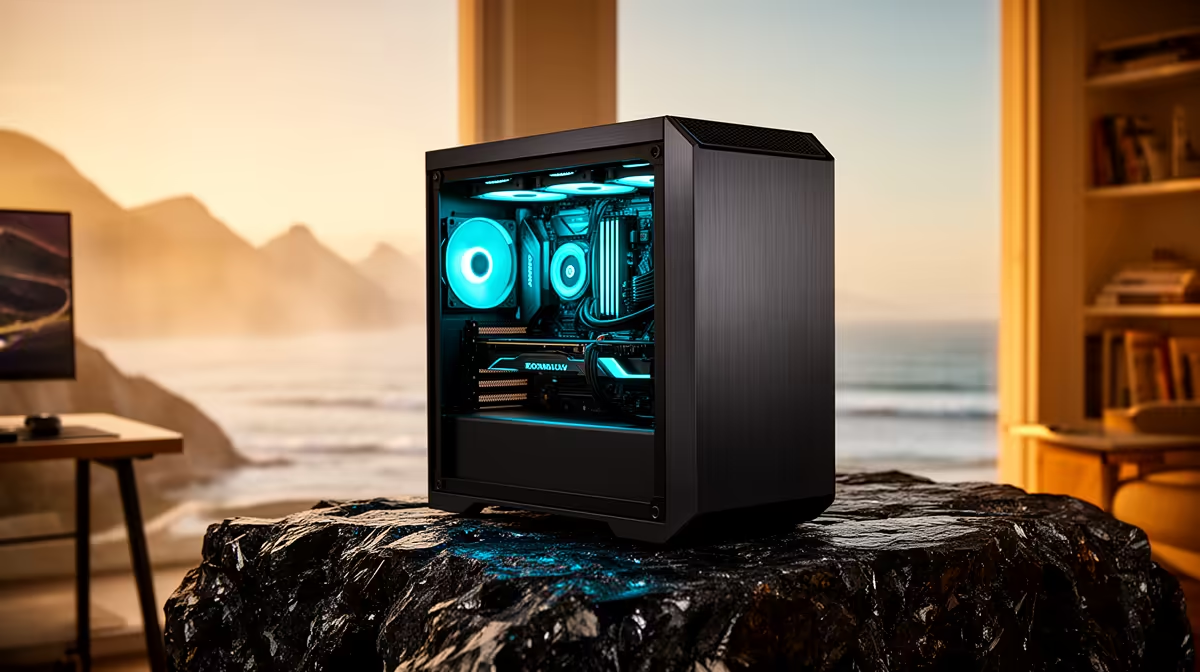
A local-LLM rig in Hermanus is sized by GPU VRAM: an RTX 4060 Ti 16 GB (~R10,500) runs quantised 7B-13B models like Llama 3 and Mistral well, and a 24 GB RTX 4090 handles 70B models. Pair the GPU with a Ryzen 5 7600 and 32 GB system RAM. For local AI, VRAM size sets the model ceiling - it matters far more than gaming frame rates.
Local language models live in GPU memory, so VRAM caps model size and speed:
System RAM (32 GB) lets you offload spillover layers to the CPU, but speed falls sharply when it does, so match the GPU to your largest model.
Hermanus is on the Overberg coast, so Evetech deliveries take 3-4 business days. Salt air means keeping the PC ventilated and off the floor; power-test before signing.
Yes. The same RTX 4060 Ti 16 GB that games well also runs 7B-13B LLMs locally via Ollama or LM Studio. Local AI just leans on VRAM and the CUDA cores rather than frame-rate performance.
A quantised Llama 3 8B generates tokens quickly on an RTX 4060 Ti 16 GB - fast enough for interactive chat. 13B models run a little slower but remain usable; speed depends on quantisation and context length.
Yes, Evetech ships to Hermanus on the Overberg coast in 3-4 business days. Power-test the GPU and confirm it's detected before signing.
files on the fast NVMe and load with GPU offload set to all layers in LM Studio - it minimises load time and avoids the slow CPU fallback that drags down token speed.
Monitor stuck at 60Hz on DDR5 build needs careful display-chain checks, not a single-part blame. Test the screen, cable, port, scaling, drivers, and setup context before replacing hardware.
Read more
Recommended build for Genshin Impact at R60 000 should justify the spend with high-end parts that help beyond one title. SA buyers should prioritise GPU headroom, large SSD space, reliable power and quiet cooling for long-term use.
Read more
Atomic Heart stuttering on RX 9070 XT points to frame pacing, driver, or settings issues first. Check display mode, shader cache, overlays, background load, and thermals before replacing parts.
Read more
Cell C Fibre Polokwane packet loss can come from Wi-Fi, drivers, router settings, Ethernet, line faults, or game-server routing. Start with local checks before replacing parts or escalating support.
Read more
University of Cape Town residence: compact should be shortlisted around the job it must do. South African buyers should compare wattage, efficiency, protection, and connector support, warranty path, and upgrade room before treating any pick as best.
Read more
UCT Actuarial Science student in Wynberg? Best needs a balanced parts plan, not a random basket. Map the CPU, GPU, RAM, SSD, cooling, and monitor target to the budget so SA builders know where to spend first.
Read more
Windows 11 spatial sound greyed out needs an output-device check before a headset purchase. Select the intended playback device and look for Windows Sonic for Headphones. Speaker, HDMI and headphone routes can expose different spatial sound options.
DisplayPort 2.1 vs DisplayPort 1.4 for aAA single-player gaming Difference explained is mostly about compatibility, budget, upgrade path, and setup fit. SA buyers should check device support and real needs before expecting a clear win from either.
RTX 4080 too expensive? Cheaper SA alternatives should solve the exact workload without overbuying. Compare nearby options by GPU tier, VRAM, cooling, and PSU headroom, local warranty path, and total build balance before moving to a product page.
Recommended build for Hollow Knight Silksong at R100 000 SA buyer's guide frames a dream-class PC around more than one game. Balance flagship graphics, premium CPU, 32GB or more RAM, fast SSDs, quiet cooling and power quality.
Windows 11 Ethernet unidentified network needs a cable, router and PC comparison before a reset. Test a second device and run the network troubleshooter. Save adapter drivers and custom settings before using network reset as the final step.
Steam processing Vulkan shaders is graphics preparation rather than a normal game download. On Linux, compare progress and repeat launches before deleting caches. A driver or game change can alter the work, so gather evidence before paying for a new GPU.
Steam discounts and events are moving towards personalised recommendations in early 2027. A firm start date is still pending. The change concerns promotional visibility, so compare the actual rand price and game requirements before making a purchase.
Windows 11 Bluetooth toggle missing can mean the radio is not being detected or enabled. Start with a complete power-off, then check the adapter and drivers. Pairing a new mouse cannot repair an absent Bluetooth control, so isolate the PC first.
Windows 11 spatial sound greyed out needs an output-device check before a headset purchase. Select the intended playback device and look for Windows Sonic for Headphones. Speaker, HDMI and headphone routes can expose different spatial sound options.
NACON Revolution 5 Unlimited adds a control screen, TMR sticks and charging dock. The controller targets PS5 and PC use, with a dedicated PC mode. Match your games and connection route before treating its premium features as a reason to replace a working pad.
GeForce NOW October 2026 games include 25 planned additions, with six in the first week. Store release dates do not guarantee instant cloud access. Check the exact game, store version, regional service and connection before changing your PC budget.
DGX Spark 64GB is a new local-AI configuration scheduled for 23 October. Its smaller unified memory pool changes workload planning. Compare model size, context and concurrency with the existing 128GB system before requesting a South African quote.