


OLED monitors Context for SA PC Builders — Updated 2026
OLED monitors talk for Randburg buyers should be treated as market context, not a live claim. Compare demand, specs, warranty, platform fit, and total build value.
Read moreA 32B Q4 model weighs roughly 20GB, but macOS only makes -70-75% of a 32GB Mac's RAM available to the GPU (-22-24GB), leaving almost no room for the KV cache or context. The result is OOM or extremely slow memory-swap inference on a 32GB MacBook.
A 32B coding model quantised to Q4 weighs in at roughly 20GB on disk, and on paper a 32GB MacBook looks like it has room to spare. It does not. macOS hands only about 70 to 75 percent of unified memory to the GPU, so a 32GB machine offers the model engine somewhere near 22 to 24GB. The weights swallow almost all of that, leaving nothing for the context window, and the result is an out-of-memory crash or inference so slow it is unusable.
No, a 32GB MacBook cannot comfortably run a 32B Q4 coding model. The 20GB of weights plus the KV cache for any real context overshoots the roughly 22 to 24GB the GPU is actually allowed to use, forcing memory swapping or an OOM. Drop to a 14B model, or step up to 48GB or 64GB of unified memory.
Unified memory on Apple Silicon is shared between the CPU and GPU, but the GPU does not get all of it. macOS reserves a slice for the operating system and apps, and tools like Ollama default to treating about 70 percent of total RAM as the usable GPU budget. On a 32GB Mac that is roughly 22 to 24GB before your editor, browser tabs and the OS itself take their cut.
Now stack the model on top. A 32B model at Q4 lands near 20GB of weights alone. That leaves only a couple of gigabytes for the KV cache, the running memory that holds your prompt and the model's working context. Feed it a few files of code to reason over and that cache balloons past what is left, and the system either errors out or starts swapping to SSD, which collapses tokens-per-second to a crawl.
A 32GB Mac is genuinely capable, just not at 32B. A 14B model at Q4 sits comfortably with room for a large context, and many of the strong mixture-of-experts coding models in the 30B class only activate a few billion parameters at a time, which keeps them responsive even though the full weights are large. For everyday code completion and refactoring, a well-chosen 14B beats a 32B model that is constantly swapping.
If running a full 32B coding model on-device is the goal, the real answer is more unified memory, not clever flags. A 48GB machine gives the GPU enough headroom for the weights and a usable context, and 64GB makes it relaxed. That is the same logic behind dedicated local-AI desktops, where high memory capacity matters more than raw clock speed. The AI PC range at Evetech is the desktop side of this trade-off for SA buyers who want to run larger models without fighting a laptop's memory ceiling, and the PC best sellers list shows which higher-memory machines are moving fastest.
Because the GPU only gets about 70 to 75 percent of unified memory, so roughly 22 to 24GB is usable. The weights take 20GB and the context cache needs several more, which pushes total demand past the limit.
You can nudge the allocation higher with a system command, but it is risky. Starving the OS of memory causes instability, and you still will not free up enough to fit a 32B model plus a real context, so it is not a genuine fix.
A 14B model at Q4 is the comfortable ceiling for coding with plenty of context. Some 30B-class mixture-of-experts models can also work because they activate only a fraction of their parameters at once.
Yes. At 64GB the GPU budget is roughly 45GB or more, which fits a 32B Q4 model and a generous context with headroom to spare. A 48GB machine is the realistic minimum for full 32B work.
Matching model size to memory is the whole game for local AI. If you want to run larger coding models without the swap penalty, compare higher-memory machines in the AI PC range at Evetech and pick the capacity your workload actually needs.
Because the GPU only gets about 70 to 75 percent of unified memory, so roughly 22 to 24GB is usable. The weights take 20GB and the context cache needs several more, which pushes total demand past the limit.
You can nudge the allocation higher with a system command, but it is risky. Starving the OS of memory causes instability, and you still will not free up enough to fit a 32B model plus a real context, so it is not a genuine fix.
A 14B model at Q4 is the comfortable ceiling for coding with plenty of context. Some 30B-class mixture-of-experts models can also work because they activate only a fraction of their parameters at once.
Yes. At 64GB the GPU budget is roughly 45GB or more, which fits a 32B Q4 model and a generous context with headroom to spare. A 48GB machine is the realistic minimum for full 32B work.
OLED monitors talk for Randburg buyers should be treated as market context, not a live claim. Compare demand, specs, warranty, platform fit, and total build value.
Read more
Ryzen X3D chips stand out in SA gaming PCs because extra cache can help frame consistency in many games. Durban builders should still compare motherboard cost, cooling, BIOS support, and GPU balance before choosing a CPU.
Read more
Ryzen X3D chips dominate many SA gaming PC discussions because extra cache can lift performance in CPU-sensitive games. Kimberley gamers should compare GPU pairing, cooling, platform cost, and upgrade timing before buying.
Read more
ROG Ally X can beat LCD Steam Deck when Windows game access, battery, and handheld performance matter most. SA buyers in Mbombela should compare controls, storage, screen, weight, and how much setup friction they will accept.
Read more
USB-C charging is becoming the standard because it cuts cable clutter and supports more modern peripherals. For SA buyers, it makes keyboards, mice, headsets, and controllers easier to charge across mixed setups.
Read more
Will the RTX 5090 handle Dragon Ball Sparking should be shortlisted around the job it must do. South African buyers should compare GPU tier, VRAM, cooling, and PSU headroom, warranty path, and upgrade room before treating any pick as best.
Read more
NVIDIA lists 550W required system power for the RTX 5060 reference specification, based on a high-end test system. A quality 550W unit can be enough, but CPU draw, transient load, connectors and ageing decide real headroom.
80+ Gold vs 80+ Platinum for couch co-op gaming is about PSU efficiency, heat, fan behaviour, quality, and wattage headroom, not direct FPS. SA buyers should compare the whole build.
Upgrade your setup with the best USB-C hubs for creators. Discover why high-capacity card readers and dual 4K output are essential for professional South African content production. 🚀💻

B850 motherboard FPS drops needs a methodical troubleshooting pass. Review drivers, thermals, power settings, background apps, cables and game settings before replacing parts in an SA gaming setup.
NVIDIA lists 550W required system power for the RTX 5060 reference specification, based on a high-end test system. A quality 550W unit can be enough, but CPU draw, transient load, connectors and ageing decide real headroom.
OpenRGB's master branch now carries changes labelled for 1.0 final, including translation and platform work, but the official tags page still lists 1.0rc3.1 as the newest packaged release. Stable users should wait for the signed release channel.
A motherboard can remain useful for many years when power, cooling and connectors stay healthy. Replace it for confirmed faults, damaged power delivery or a blocked platform need, not simply because the calendar reaches a fixed age.
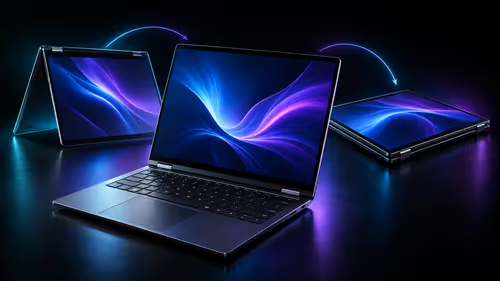
The VAIO T combines a 13.3-inch display with a multi-flip mechanism for laptop, tablet and outward-facing viewing modes. Orders begin in Japan on 18 September; South African availability is unconfirmed.
OLED monitors talk for Randburg buyers should be treated as market context, not a live claim. Compare demand, specs, warranty, platform fit, and total build value.
Wi-Fi 7 vs Wi-Fi 6e for aaa single-player gaming comes down to router support, latency goals, device compatibility, and coverage. SA buyers should match the choice to the real network setup.
Ryzen X3D chips stand out in SA gaming PCs because extra cache can help frame consistency in many games. Durban builders should still compare motherboard cost, cooling, BIOS support, and GPU balance before choosing a CPU.
Wi-Fi 7 and Wi-Fi 6E affect AAA single-player gaming through downloads, updates, cloud saves, and remote features. The real world difference between wi fi 7 and wi fi depends on your router, fibre speed, and SA home layout.