Running a large AI model on your own machine, rather than someone else's server, comes down to one question that has nothing to do with reputation or marketing: does the model actually fit in the memory you have.
Quick Answer
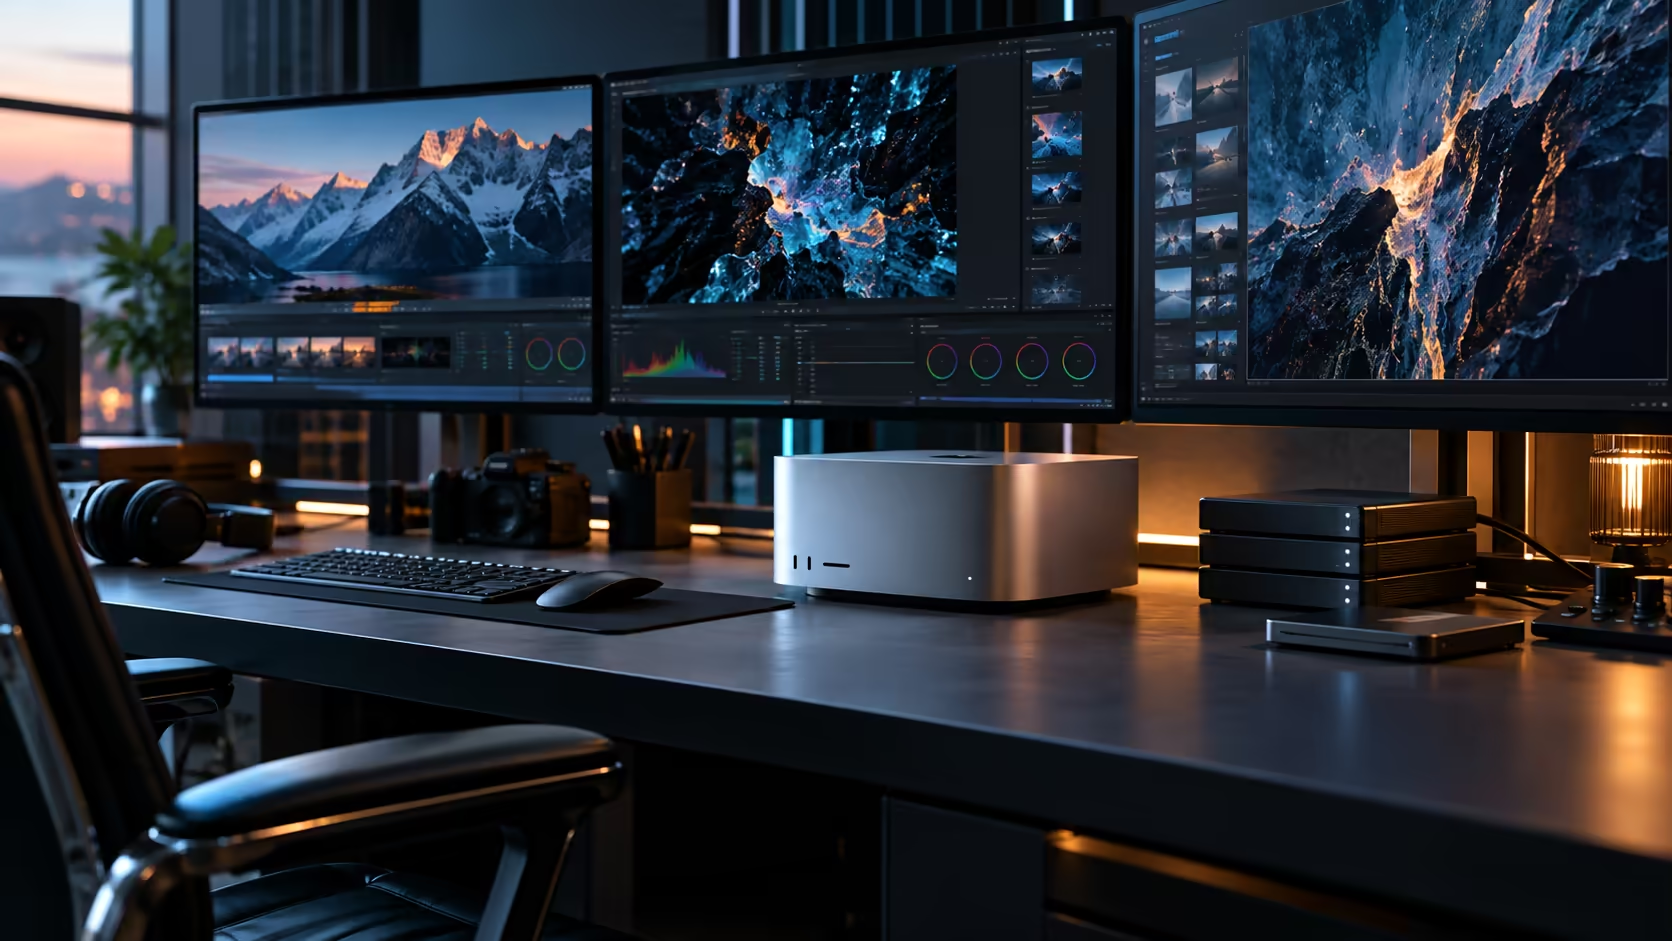
Yes, within the limits of its memory. The M5 Ultra configuration at Evetech carries 96GB of unified memory shared between the processor, graphics cores and Neural Engine, and that pool is what decides which models fit comfortably and which don't. It lists at R108,999.
📏 Why the model's published requirement is the only number that matters
Skip general claims about AI capability and go straight to the figure that actually decides the outcome.
Every release comes with its own publisher-stated memory footprint at each quantisation level, and lining that figure up against 96GB is a five-minute check that beats any amount of reading about how "AI-capable" a machine supposedly is. A 96GB pool, backed by a 1TB internal SSD for storing the model files themselves, covers a considerably wider range of models than a smaller configuration, but it isn't limitless, and the largest releases can still exceed it once you account for macOS and whatever else is running alongside the model.
🧠 What the shared memory pool actually buys you here
The architecture is what makes running a large model on this machine practical rather than merely theoretical.
The chip's processor, graphics cores and Neural Engine each reach into the same 96GB space rather than holding a private slice of their own, so a loaded model simply stays where it is, available to whichever one needs it next, with no copying step in between. A tower built around a single graphics card works very differently: once a model outgrows that card's own VRAM, it either refuses to load or gets awkwardly split across mismatched memory pools.
⚖️ Running a model alongside other demanding work
The comfortable headroom a model shows in isolation shrinks the moment real multitasking enters the picture.
A language model running beside an 8K timeline, a large 3D scene or several other memory-hungry applications draws on the identical 96GB pool those tasks are already using. Fire up that exact combination and watch it under real conditions rather than judging the model by how it behaves with nothing else open, especially if the plan is for AI to run continuously through a demanding working session rather than as an occasional standalone task.
Frequently Asked Questions
What determines whether a large language model runs on the Mac Studio M5 Ultra?
The model's own published memory requirement compared against the available 96GB pool, accounting for macOS and any other applications running at the same time.
Is 96GB always enough for the largest available models?
Not always. The largest open-weight releases can still exceed 96GB once other memory demands are accounted for, so check the specific model's requirement rather than assuming this tier covers everything.
Does the Mac Studio M5 Ultra handle AI work differently from a Mac mini?
Both share the same unified memory architecture, but the M5 Ultra's larger 96GB pool and stronger GPU support meaningfully larger models than the Mac mini tier.
Can I run a model alongside heavy creative work at the same time?
You can, but the shared 96GB pool is what limits it. Test your actual combined workload directly, since both draw from the identical memory space.
Ready to check whether your target model fits this configuration?
Compare its published memory requirement against the Mac Studio M5 Ultra's 96GB pool before committing.